![Busy port scene with stacked shipping containers, large cranes, and cargo ships in a bay, beside a coastal highway and rail line on the right.] }} (Note: The input requires a valid JSON with an array of strings in altTexts. Here is a corrected version.)Let's provide proper JSON.](https://www.supplychaininforms.com/wp-content/uploads/2026/09/trade-and-logistics-infrastructure-218x150.webp "Turkey Looks to Upgrade Trade and Logistics Infrastructure")





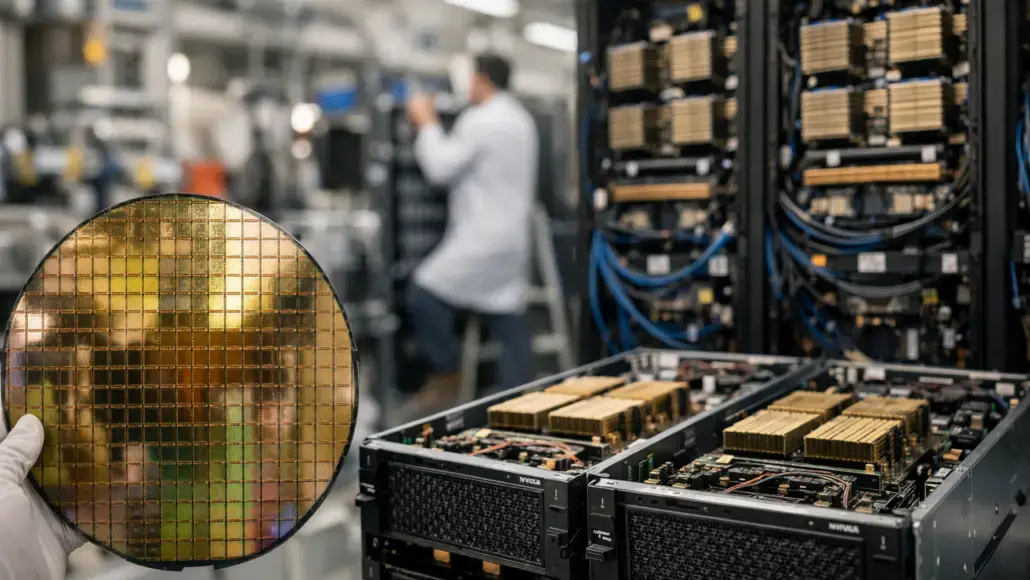
NVIDIA has one of the biggest and most intricate supply chains in the world, and its efficacy is measured from wafer-out to first token.
The interval is in two sections. Time-to-rack covers silicon leaving the fab to an installed system that arrives on a data center floor. Time-to-token includes everything that comes after – be it power, cooling, networking, and the software stack, which makes the infrastructure efficient on day one.
It is worth noting that NVIDIA Grace Blackwell NVL72 platforms are made up of millions of parts and thousands of suppliers from around the world and then assembled into the final system by dozens of OEMs and ODMs.
One compute tray alone – one of eighteen in a rack – calls for two NVIDIA Grace CPUs, four NVIDIA Blackwell GPUs, and thirty-two stacks of HBM3e. The supply chain that has been built for Vera Rubin is twice as much as that of Grace Blackwell. CPUs, GPUs, and memory are all essential parts, and the presence of each changes from week to week. So the part retaining build one week may be readily accessible the next.
Each has its own bill of materials, its own suppliers, and its own lead times. Multiply that by each sub-assembly in the rack, and you start to have something that looks less like a supply chain and more like a challenging combinatorics problem.
Contract manufacturers cannot begin an assembly until all the components are received from one of three pools – parts received directly from NVIDIA, parts that NVIDIA holds on consignment, and parts coming from suppliers. Ideally, all the components arrive together, but when they don’t, whatever was delivered early waits for everything, which is late. NVIDIA measures the time from when a manufacturing site gets a material to when it ships it out as part of a sub-assembly or product. That time is referred to as Time of Ownership, or TOO.
Availability changes a lot, so NVIDIA has to decide what to make and how much of it to send to each factory. This is the critical material allocation problem, and it is revised by hand every week. The allocation covers the current and next quarters, and the closest weeks are already allocated, so most of the new data each week will simply change what occurs further out.
We are mostly talking about time-to-rack, and compression of it involves four things –
- Real-time visibility to identify critical operational bottlenecks anytime
- Single point of failure replication to prevent production stoppage
- Reliability to maintain upstream production commitments
- Human expertise codified, so the rationale behind a complicated allocation decision becomes a lasting knowledge that expands over time
The first three requirements establish the operational baseline we need, but it is the codification of human expertise wherein the most major shift takes place.
Coming up with a Supply Chain Command Center in Palantir Foundry
The NVIDIA supply chain operations team partnered with Palantir to build a unified view of all inputs to a material allocation decision. It’s what the NVIDIA team refers to as their Digital Supply Chain Intelligence command center, which brings to light risks and blockers as well as other signals that guide those decisions but may have been hidden across disjoint data sources in the past.
In the background, Palantir Foundry offers the operating context. The ontology brings together materials, manufacturing locations, pledges, capacity, allocations, production outputs, and unstructured, qualitative signals into a single governed data level. It is made up of links and objects as opposed to tables and rows and gives a complete picture of operational reality.
This representation allows allocation planners to replicate and analyze a variety of scenarios, giving them much more extensive access to the decision space and creating the foundations for an AI flywheel that builds new information and enhances performance over time.
Addressing the quantitative side with NVIDIA cuOpt
The first step in the formulation of the problem is to define the decision variables, the quantities of each restricted material to be assigned to each of the sites and when during the coming period. Around them sits all that limits the answer. That’s all the manufacturers that can make a given Blackwell sub-assembly, and the capacity each site can take in once the material lands. It also has the dependency graph of each needed piece mapped backward through the chain so the solver knows a compute tray is blocked by its most scarce input and not by its average input.
The binding restriction is not fixed. It alternates between the following:
- Week over week GPU, CPU, and memory
- Inbound timing for each of the three supply routes
- Existing commitments to customers that set the real cost of a shortage at any one site
- Thousands of variables and constraints boil down to one allocation per week
NVIDIA cuOpt — which is an open-source library for GPU-accelerated decision optimization – tackles this. It is fed by the ontology and writes the outcome as an allocation decision. The allocation is formulated as a mixed-integer linear program with the objective to minimize Time of Ownership – TOO. cuOpt provides more than just the allocation. It also tells you which limits are binding, so a planner can see it was Taiwan capacity and not memory supply that held this week’s number down.
The solution is fast, so the planners are able to explore the space around the answer. What happens if one has 10% less memory this period? What if a new production site comes on stream? Planners shift from asking a solution provider for an answer to asking the solver about the trade-offs.
Where the math ends
Quantitative optimization is not the whole story. NVIDIA and Palantir back-tested historical allocation choices against what actually happened, and it showed a human factor that cuOpt did not succeed in capturing.
Planners drew on data unavailable to the solver – emails that week with partners, a forecast of bad weather in a critical region, a current geopolitical event, the recording from the last supplier summary, and years of collective experience. These inputs feed a feeling for how to allocate material for the next period, and that innate sense is what makes the human specialists better compared to the math.
So with that in mind, NVIDIA and Palantir constructed this workflow around those human experts. It documents the allocation decision, the rationale, the anticipated outcome, and the real outcome. And because that data exists in the ontology, it becomes the basis for educating an LLM on expert judgement.
Decision Intelligence Codification
We then post-train an open-weight LLM to leverage that identical reasoning and make a suggestion. We evaluated the open models from NVIDIA Nemotron and selected Nemotron 3.5 Lightning because it is designed for the implementation layer of an agentic workflow. It performs specialized tasks in a system of models, including larger variants for orchestration and general tasks.
Its mixture-of-experts architecture makes it very efficient for inferring, and while the model is thin at 30 billion parameters, just 3 billion active per forward pass, it is large enough to acquire a focused policy. The post-training loop is practical with this footprint. Smaller models learn faster and require much less computation to train and deploy compared to larger counterparts.
Nemotron is open; consequently, you can post-train it internally within your own computation boundary. Any organization can run the same fly wheel on their own operational data by externally exposing it. The model is trained on signals used by planners in practice – the quantity of limited material provided to a manufacturing site, the commitment of the manufacturer to create what was produced, and the qualitative operational proof available at the time of the choice.
The goal is to formalize an allocation policy that can evaluate the risk of production, propose an allocation range, determine why it is recommended, and clarify its rationale to the supply chain team. It is well to be noted that the record itself is the evaluation harness.
We re-run each decision with only what was known that day, we keep the outcome hidden, and then we contrast the model’s recommendation to the planner’s call and what truly transpired. The main question this assessment answers is – If this model had been operational last month, would it have made a suitable allocation decision?
From Ontology data to a specific model
The training process begins with operational history in the Palantir Ontology –
- Anonymization – NeMo Anonymizer eliminates personally identifiable information and masks sensitive fields before training.
- Synthetic data generation – NeMo Data Designer generates and reconciles the examples, so the model is trained on not just routine weeks, but also allocation rises, limitations on capacity, and disruption situations.
- Supervised fine-tuning – NeMo AutoModel trains using a small set of LoRA adapter parameters while keeping the base weights frozen, reducing training duration, memory specifications, and checkpoint size.
- Evaluation – The point-in-time backtest applies the same historical decisions to the base and fine-tuned models so as to isolate the effect of post-training.
Palantir Autopilot goes on to manage the full lifecycle, starting each job from ontology data, keeping track of the deployed custom Nemotron model, and maintaining a lineage from data to model variant to suggestion.
Once implemented, the model reads the present operational context and generates a recommendation with its justification and associated risks. A planner looks at it and makes the decision.
Closing the loop
Each approval, edit, override, and production result is written back to Ontology and accumulates until adequate representative data is available so as to rationalize another governed training run.
The feedback will be utilized for reinforcement learning in the future. Preference works with rewards for accuracy of allocation, adherence to policy, and a foundation in evidence that would be generated by embraced and overruled recommendations. The model is never retrained in production.
The outcome compounds in two ways. Planners spend less time rebuilding routine choices, so they encompass more sites and products, and allocation skills also serve as institutional expertise, simplifying onboarding and spreading important insights across the organization.
What post-training did
Palantir was used by the supply chain operations team from NVIDIA so as to define the model inputs, what it can recommend, and how the suggestions are scored. That workflow then became the application and the decision-intelligence standard for allocation.
Three models were compared on the same assignment and same evaluation data –
- Base Nemotron 3.5 Lightning (BF16)
- Nemotron 3 Ultra (NVFP4)
- Our post-trained Nemotron 3.5 Lightning (BF16)
After training, the Lightning model achieved 86.7% allocation-decision accuracy on the development standard. Ultra was 55.5%, and lightning was 17.5%, which leaves the post-trained model 31.2 percentage points in front of Ultra and 69.2 ahead of its own base model.
It also leads on the two metrics that give equal weight to decision types instead of examples. Balanced accuracy averages recall over classes, so rare calls are as important as common ones.
58.6% compared to Ultra’s 42.0%. Macro-F1 averages per-class F1, including precision so a model can’t boost recall by over-predicting a rare class – 57.5% vs. 39.5%. Both. If supply is constrained, then planners will reduce allocations much more often than they will increase them, so plain accuracy would flatter a majority-class guesser.
The lesson is specific but important – On a bounded allocation task, a specialized 30B model can go ahead and outperform a general-purpose model, which, by the way, is more than an order of magnitude larger.
This doesn’t mean the smaller model is more capable in general. Its improvements are specific to the domain on which it was post-trained. Fine-tuning did not make forecasting future production risk any easier. Specialization improved the decision task but did not solve all attached prediction problems.
The LoRA run took minutes on 2x NVIDIA B200 GPUs, light enough to run again as feedback accumulates. This is sovereign AI in action. Proprietary supply chain data, model weights, and inference all remain within a single governed setting. The AI stack can be deployed on-premises or in the cloud so organizations can run AI where their data, systems, and operational needs demand it.
A learning supply chain
The supply chain workflow discussed in this post is not unique to semiconductors. Any operation in which critical capacity is assigned by experienced people working from fragmented signals may utilize the same flywheel and adapt it to new domains.
This needs three essential things –
- An operational layer under control
- Decision capture rationale and outcome
- An open model that can be fine-tuned within a secure compute boundary
The model is trained on operational data, and the model improves the decision, and the decision generates new operational data for the next round of governed training. That is how NVIDIA and Palantir compress wafer-out to first token, and it is how the most reliable AI infrastructure supply chain in the world learns faster compared to it grows.